
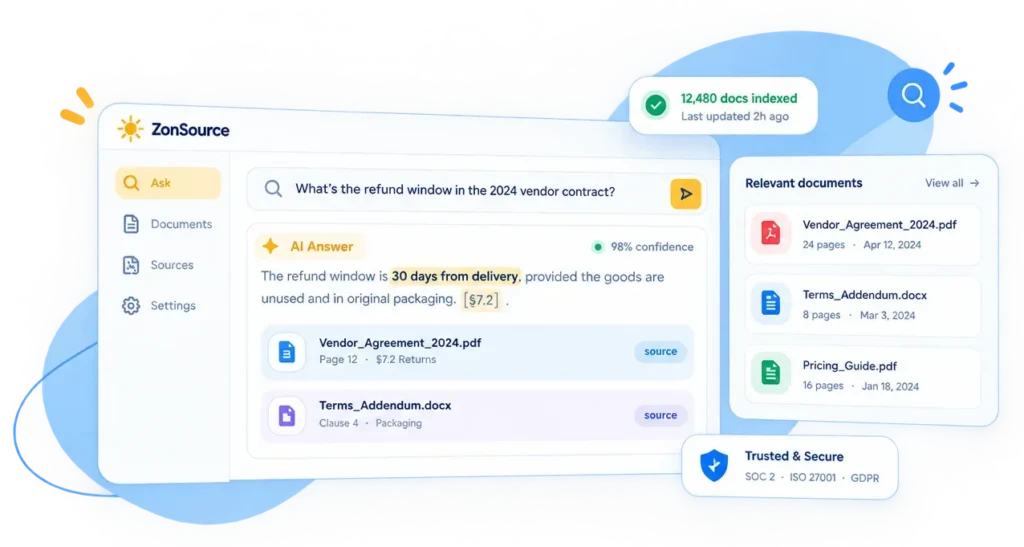
Turn documents into instant, integration for cited answers.
Extraction pipelines + semantic knowledge search, in production.
We build AI that reads, extracts, and understands your documents — then lets your team ask questions in plain language and get answers with the source, right inside the tools they already use.
AI Document Processing & Knowledge Search
Document Types Parsed
0
+
From Upload to Answer
0
S
Every Answer Sourced & Cited
0
%
ISO Certified Security
0
The Problem
Your knowledge exists. Your team just can't reach it.
Documents pile up faster than anyone can read them, and the answers your team needs are locked inside files no one can search.
Knowledge is buried
Answers live in PDFs, wikis, tickets, and email — nobody can find them fast.
Manual data entry
Teams retype invoices, forms, and records by hand. Slow, costly, error-prone.
Keyword search fails
Ctrl+F and legacy search miss anything not worded exactly right.
No source of truth
Two people get two answers. Neither can prove which is correct.
Capabilities
What we build. From raw files to answers .
Two connected systems — a document processing pipeline that structures your files, and a knowledge search layer that makes them instantly answerable.
Document Extraction
Pull structured data from invoices, contracts, forms, and records — OCR + LLM parsing that reads even messy scans.
- Tables, fields, line items
- Handwriting & scanned PDFs
- Validated against your rules
Auto-Classification
Every incoming document is identified, tagged, and filed automatically — no manual sorting.
- Doc-type detection
- Metadata tagging
- Confidence scoring
Semantic Knowledge Search
Ask questions in plain language across your entire document base and get answers, not just links.
- Meaning-based retrieval
- Cited answers
- Hybrid keyword + semantic
Summarization & Q&A
Long contracts and reports distilled into the answer you need — with the exact clause it came from.
- Per-document summaries
- Cross-document synthesis
- Source attribution
Extraction Pipelines
End-to-end pipelines that ingest, process, validate, and route documents into your existing systems.
- Batch & real-time ingest
- Exception handling
- Pushes to your DMS/ERP
Knowledge Assistants
A chat assistant grounded in your knowledge base — answering staff and customers with your own content.
- Grounded in your data
- Always-current answers
- Embeds in your tools
How it works
From inbox to answer, in one pipeline.
Every document that enters your business runs a controlled path — parsed, structured, indexed, and made answerable — with validation at each step.
01
Ingest
Documents flow in — upload, email, API, or a watched folder in your DMS.
02
Extract
OCR + LLM parse text, tables, and fields, even from scans and handwriting.
03
Structure
Data is classified, validated against your rules, and normalized.
04
Index
Content is embedded into a vector store for meaning-based retrieval.
Human review checkpoints and confidence thresholds guard every extraction.
Semantic search
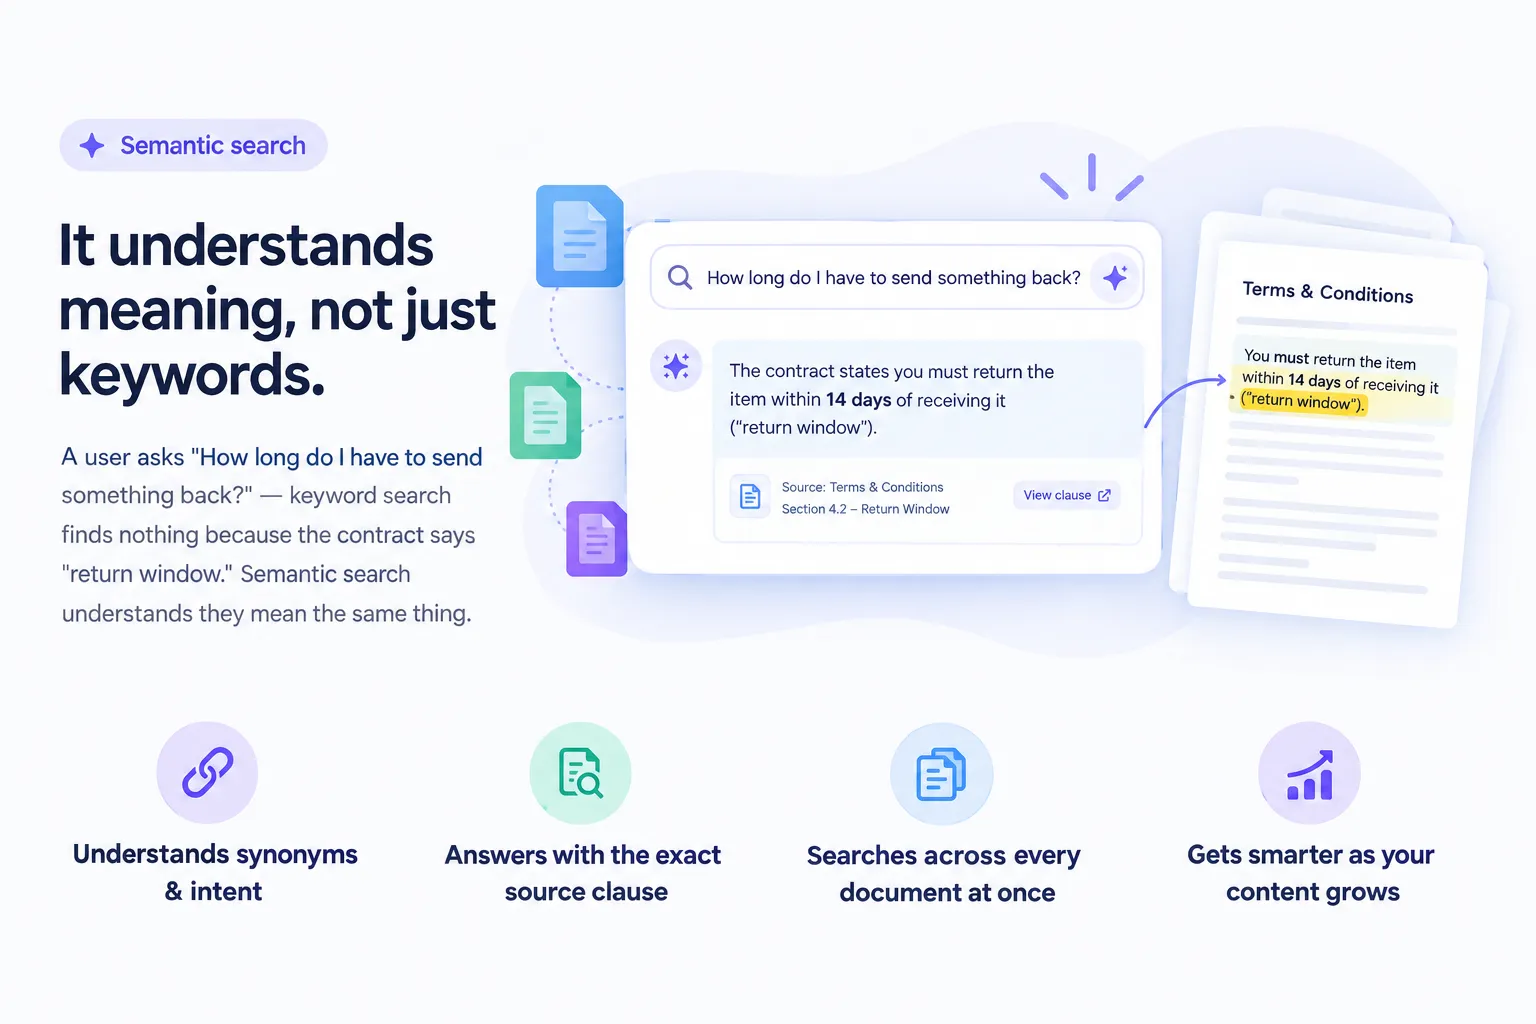
It understands meaning, not just keywords.
A user asks “How long do I have to send something back?” — keyword search finds nothing because the contract says “return window.” Semantic search understands they mean the same thing.
- Understands synonyms & intent
- Answers with the exact source clause
- Searches across every document at once
- Gets smarter as your content grows
Security & Trust
Built for sensitive documents.
Contracts, records, and financials demand more than a demo. Governance is engineered into the pipeline.
Your data stays yours
Documents are processed in your tenant or private cloud — never used to train public models.
PII detection & redaction
Sensitive fields identified and masked before anything reaches an external model.
Permissioned answers
Search respects your access controls — users only see what their role permits.
Full audit trail
Every query, answer, and source access logged and traceable.
On-prem option
Self-hosted models and vector stores where data cannot leave your infrastructure.
Source-grounded only
Answers are generated from your documents with citations — no hallucinated facts.
ISO 27001:2018 certified · HIPAA, SOC 2 & GDPR-aligned deployments
Where it earns its keep
Built for the teams buried in paperwork.
Legal
Contract review, clause search, obligation tracking
Finance
Invoice extraction, statement parsing, reconciliation
Healthcare
Records summarization, intake forms, prior-auth
HR & Ops
Policy Q&A, onboarding docs, SOP search
Insurance
Claims documents, policy lookup, form extraction
Support
Knowledge-base answers, ticket deflection
Real Estate
Lease abstraction, title docs, disclosures
Research
Literature search, report synthesis, citations
FAQ’s
Questions teams ask us.
What document types can you process?
PDFs (including scans), Word, Excel, images, emails, and more — 20+ formats. OCR handles scanned and even handwritten documents; LLM parsing extracts tables, fields, and line items.
How is this different from keyword search?
Keyword search matches exact words. Semantic search understands meaning — so “how long to send something back” finds a clause about “return window.” Answers come with the exact source citation.
Will answers be accurate, or will it hallucinate?
Answers are generated only from your documents and always cite the source. If the answer isn’t in your content, the system says so rather than inventing one.
Does it work with our existing systems?
Yes. It ingests from your DMS, drives, email, or APIs, and pushes structured data into your ERP, CRM, or database. Search embeds inside the tools your team already uses.
How do you handle sensitive documents?
Processing runs in your tenant or private cloud, PII is detected and redacted before any external model call, answers respect your access controls, and everything is audit-logged. ISO 27001 certified.
Can it run fully on-premise?
Yes. For regulated data we deploy self-hosted models and vector stores on your infrastructure so documents never leave your environment.
What the assessment delivers
- A map of your document types and where they live
- The highest-ROI extraction or search opportunity
- Recommended pipeline & search architecture
- Data security and access-control plan
- A suggested first deployment, with timeline
- Reply within 24 hours
- Senior AI engineers only
- NDA friendly · ISO 27001
- Delivered in 1–2 weeks
ZonSource IT Solutions Pvt. Ltd. ®
Innovative solutions for a digital world.
Talk to us
- 1 (407) 768-0986
- +91 9599902185
- Community Centre, Block C, Janakpuri, New Delhi, Delhi, 110058
- 1317 Edgewater Dr #5286 Orlando, FL 32804, United States
- 189 Queen St Melbourne VIC 3000 Australia
Copyright © 2026 ZonSource IT Solutions Pvt. Ltd. ®